Own productTrading / research
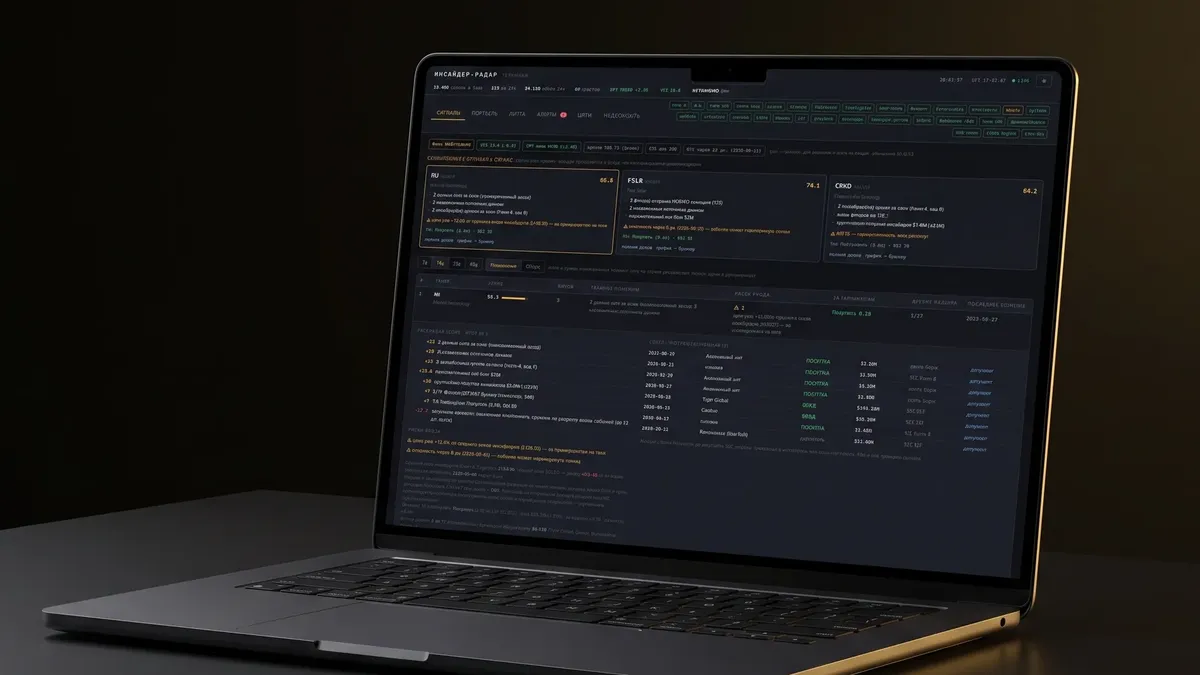
Insider Radar, smart-money signals with an honest track record
26Sources in one score
1/7/30 dOutcome checks per signal
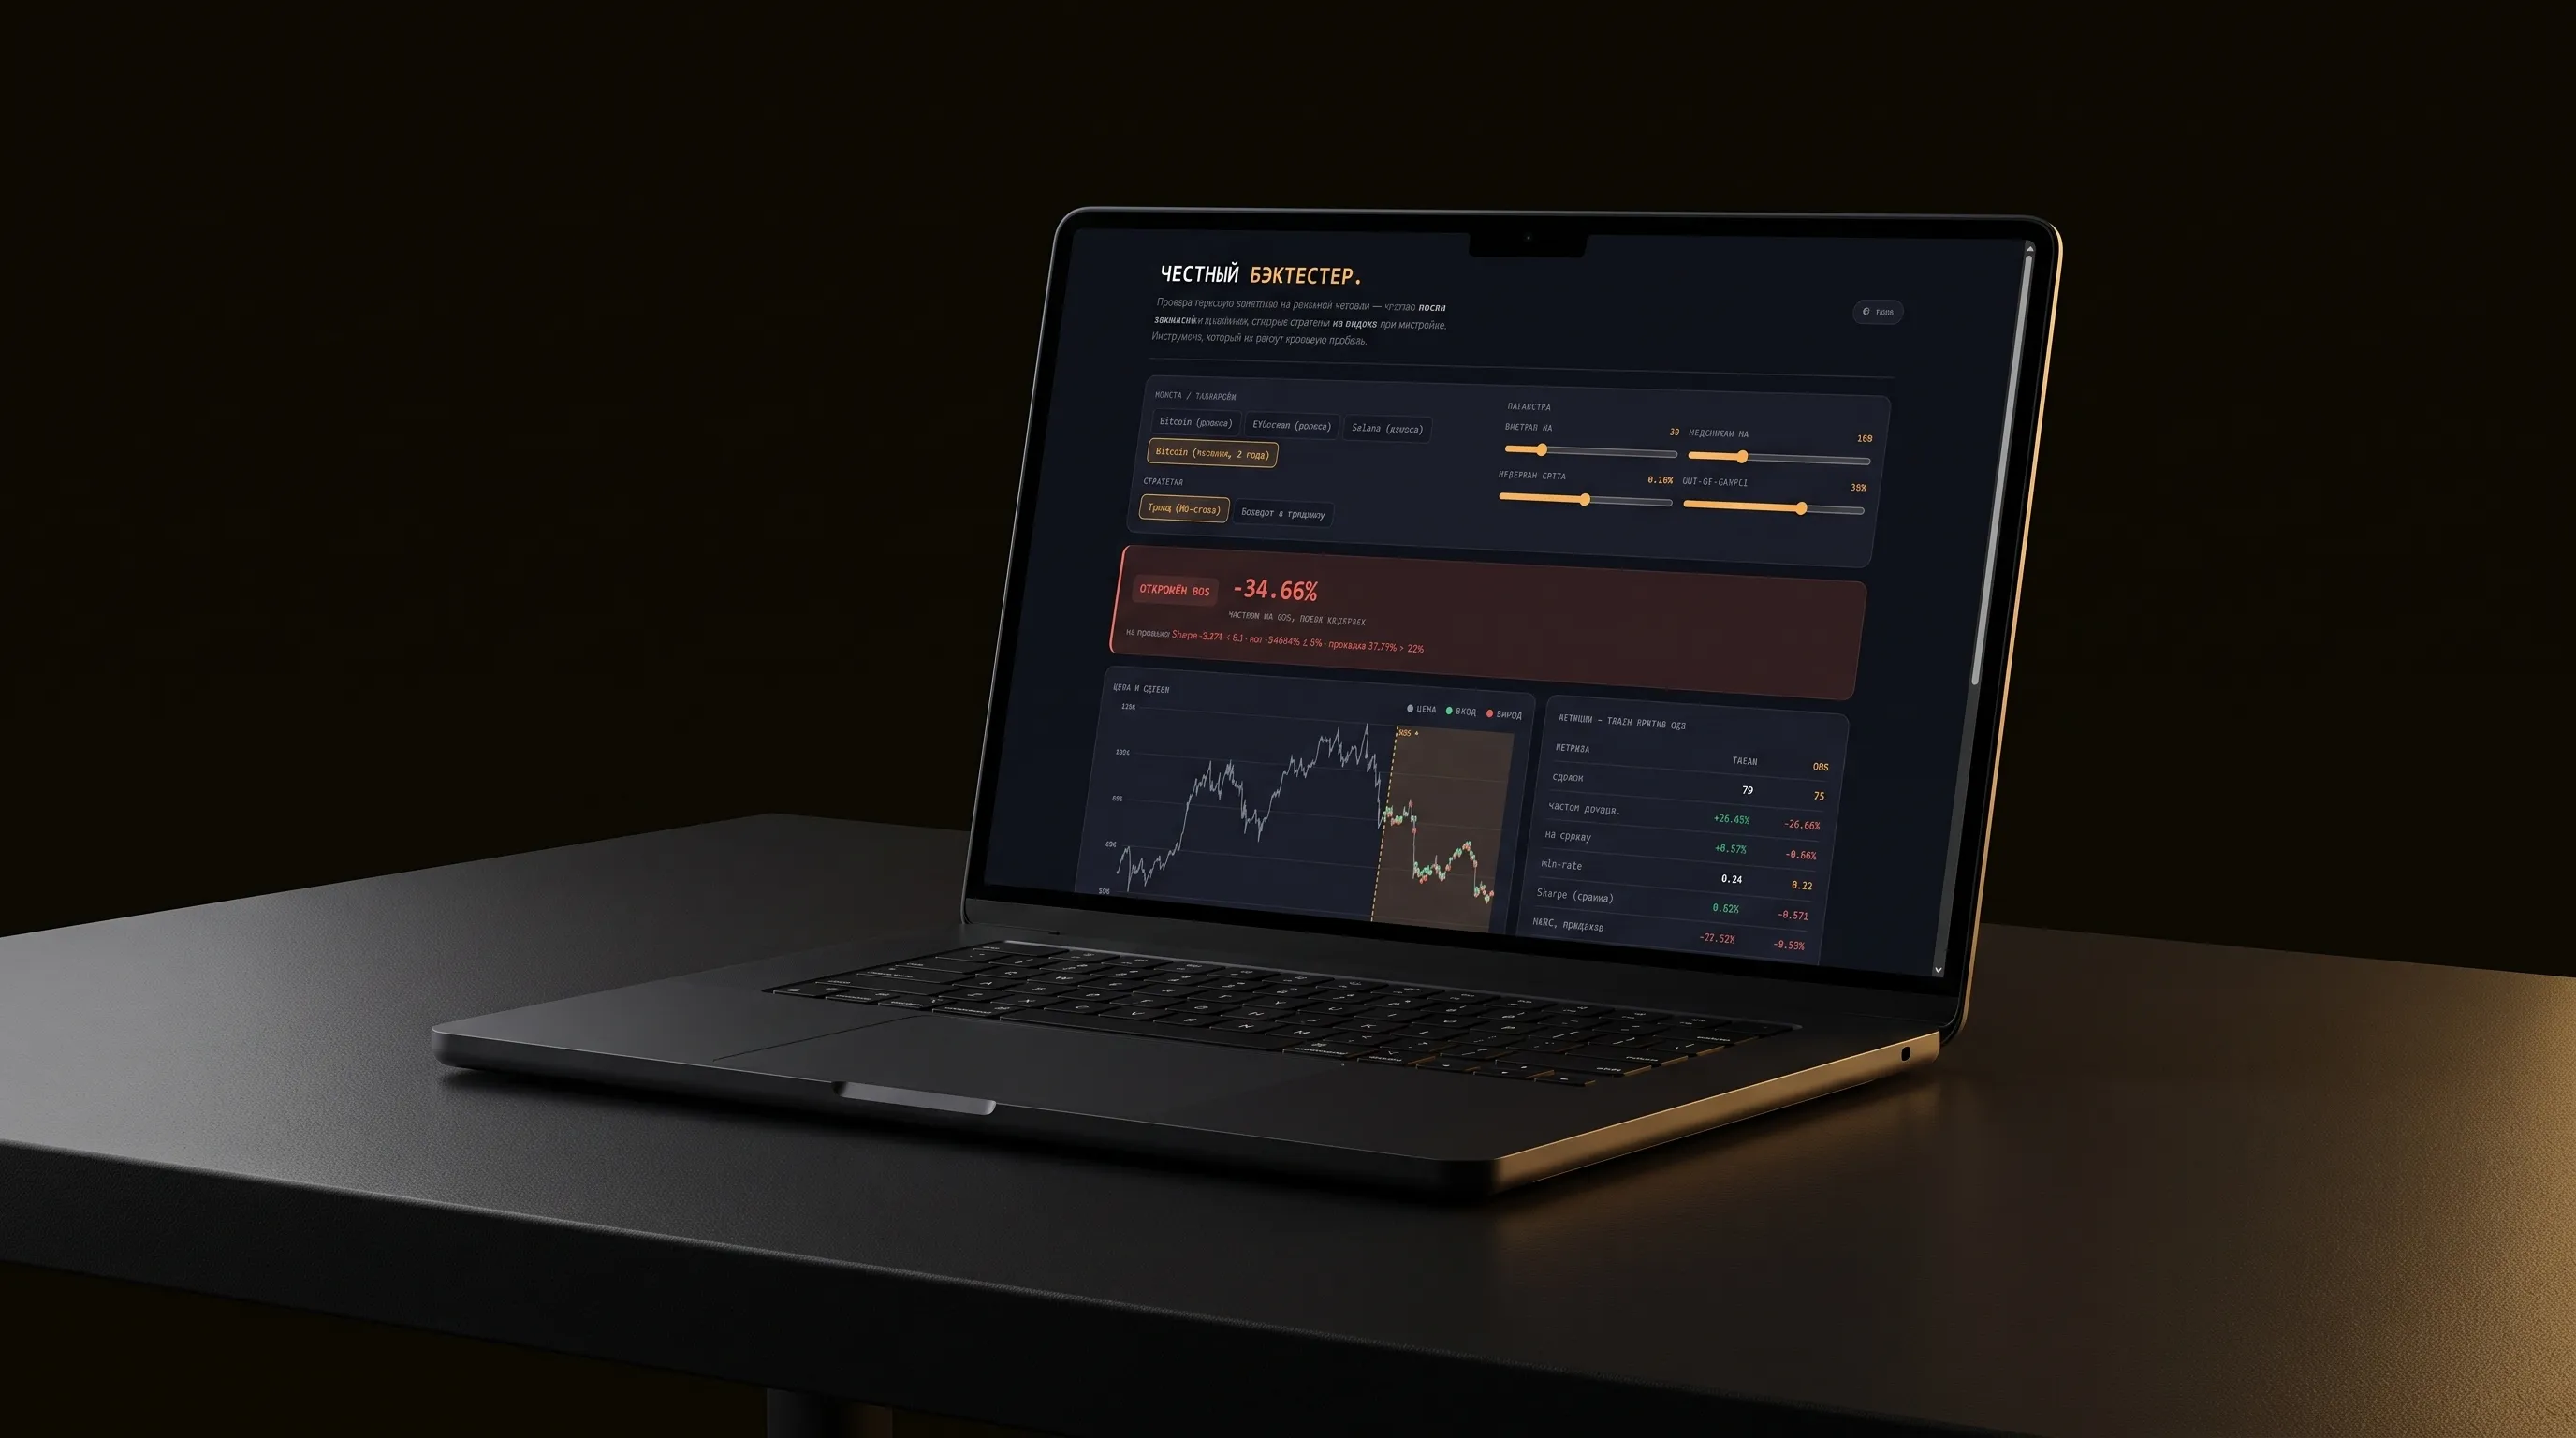
One NautilusTrader engine runs the same code in backtest and live, the judge scores only data the strategy has never seen, and the verdict gets published even when the answer is no.
Covering the OOS judge, evaluate.py
0.3% and 0.4% round trip
Built with Claude Code in 1 day
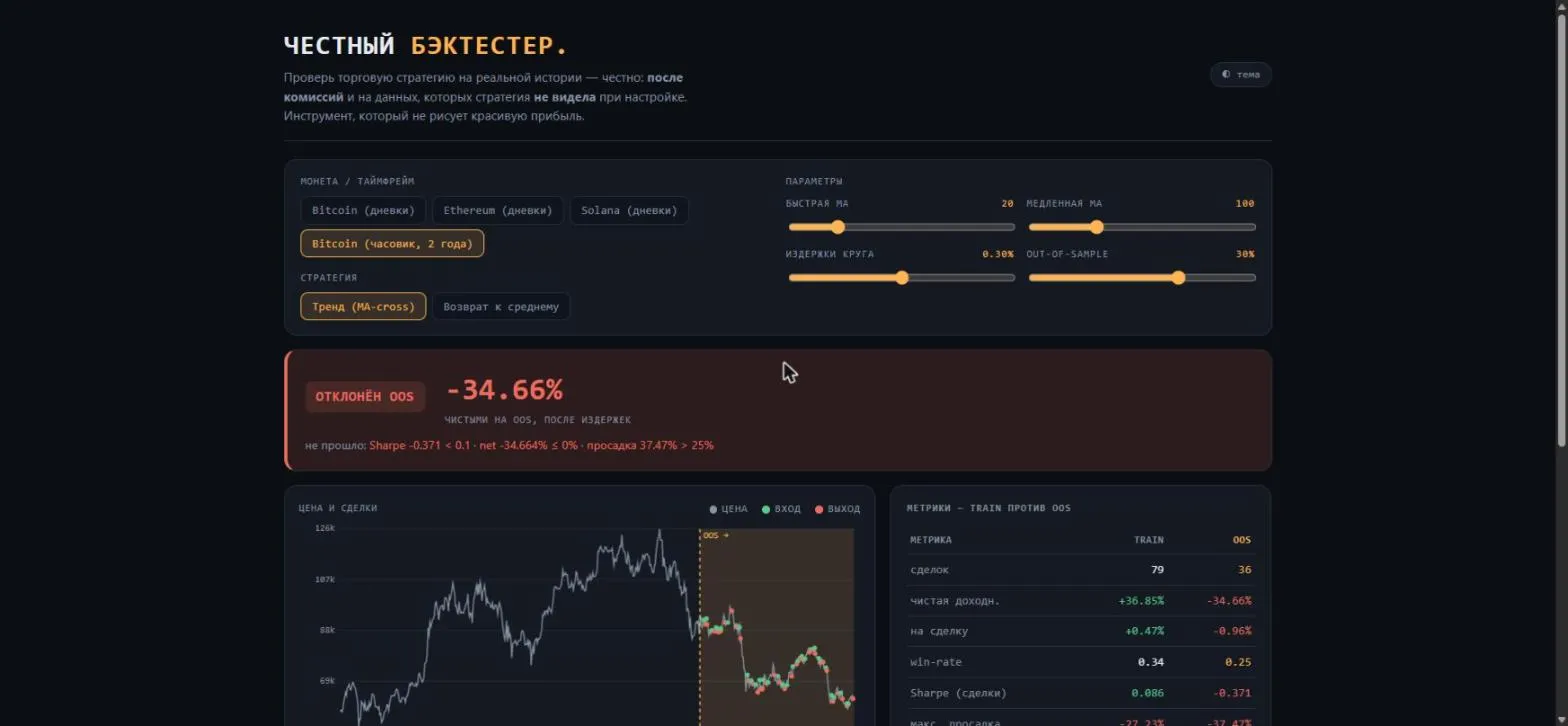
Choose the market, the strategy and the cost level, and the tool shows the out-of-sample result with the kill criteria that decided the verdict. The browser runs its own calculation and matches the Python backtest to the digit.
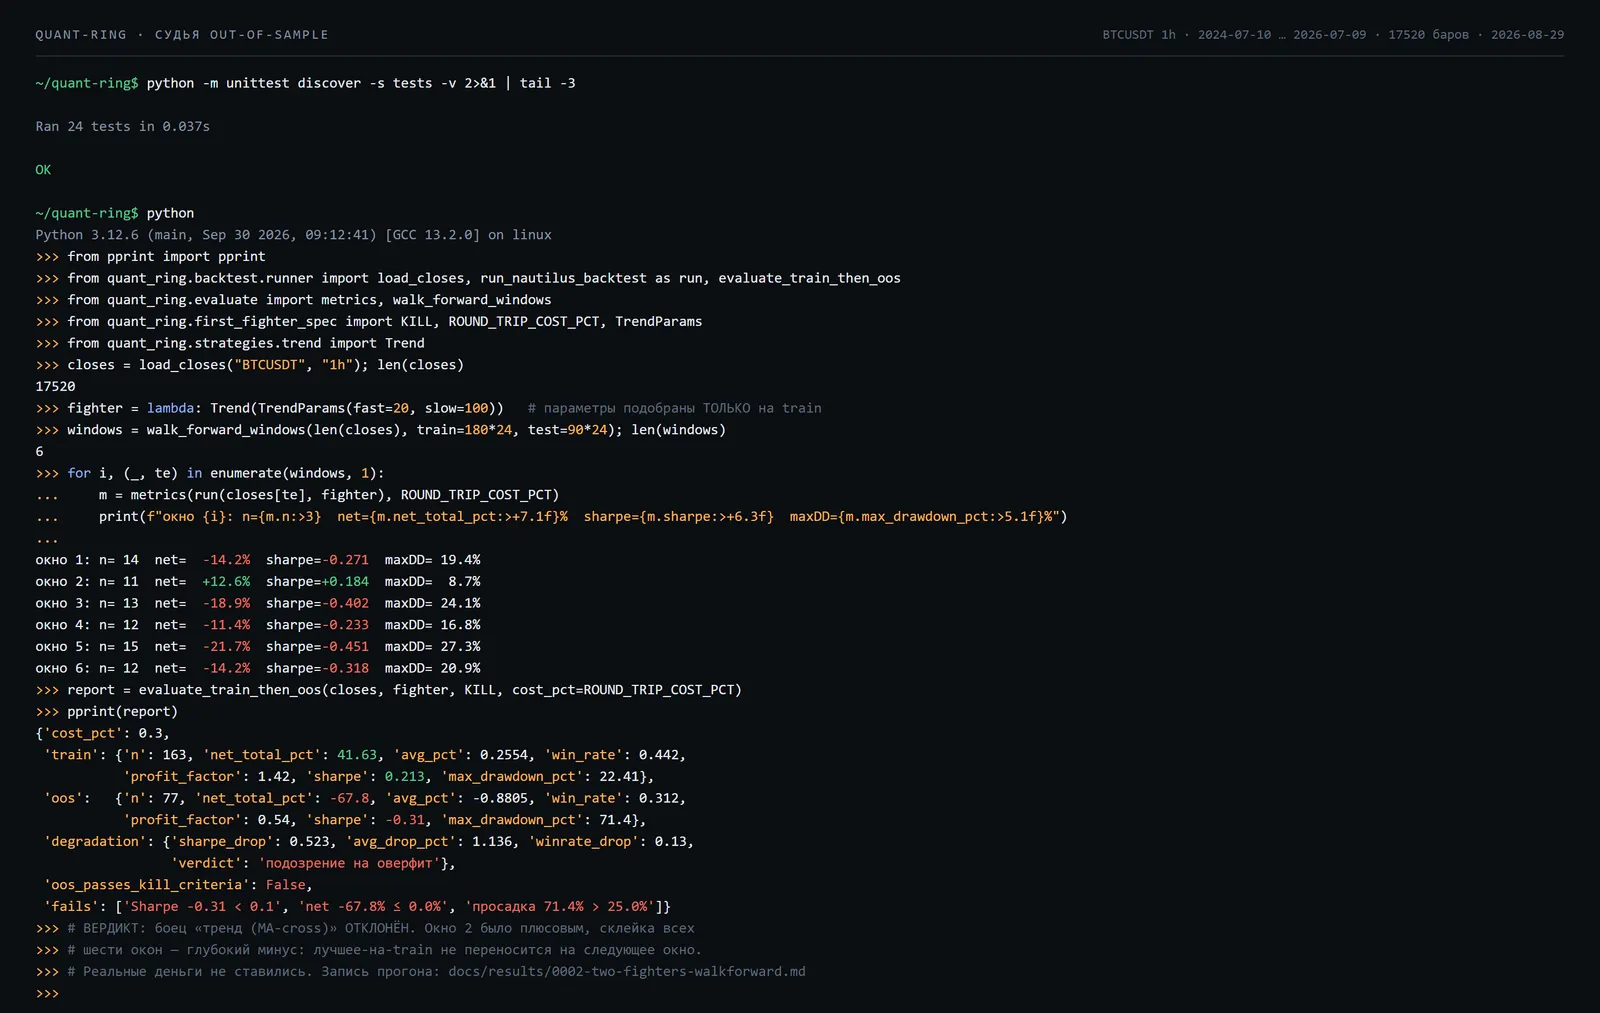
evaluate.py splits the history, walks forward through six windows and prints net result, Sharpe and drawdown for each one. A single green window saves nothing, because the kill criteria read the whole sequence, and 24 tests guard the judge itself.
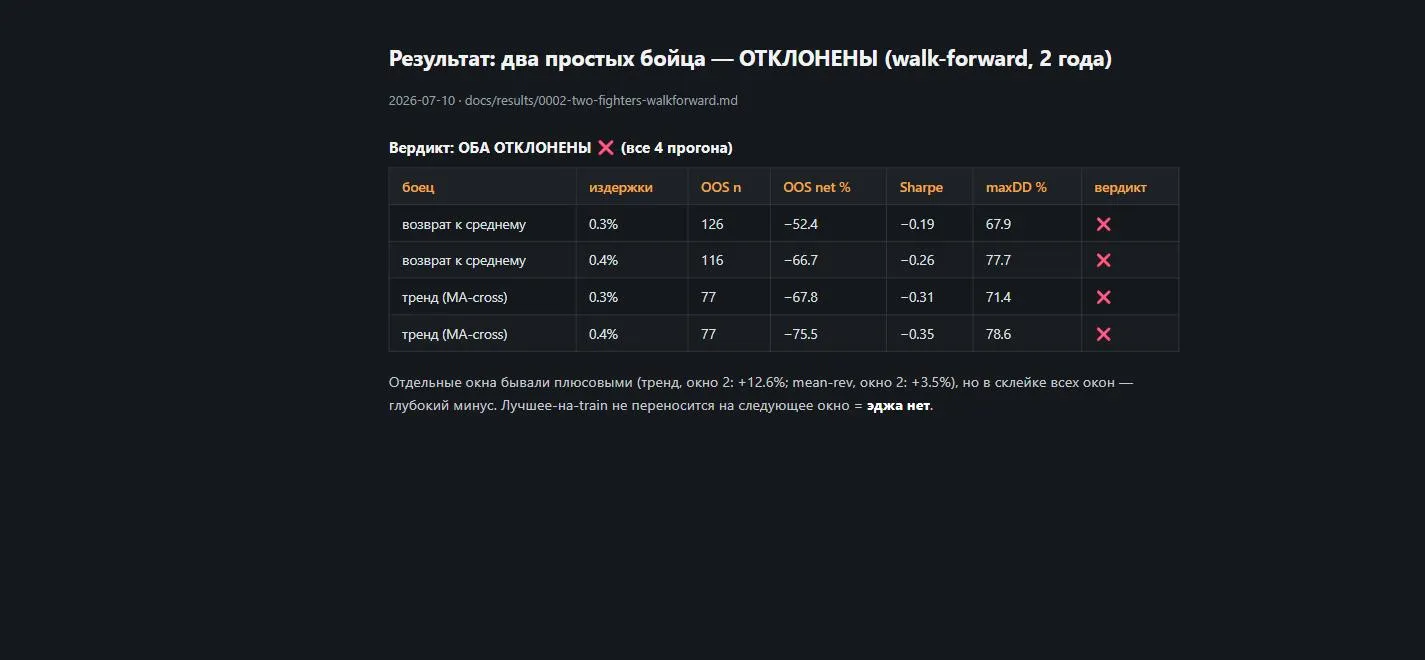
Four runs, two strategies and two cost levels. Each row carries the out-of-sample trade count, net result, Sharpe and drawdown next to a rejected verdict. A negative result ships in the docs and never gets quietly retried with new parameters.
A curve that looked perfect on the tuning data hid the fact that there was no edge.
Six walk-forward windows, real fees and one verdict, rejected and published in full.
01Context
Crypto strategy projects usually ship the exciting part first, a strategy that backtests beautifully, then loses money live because the backtest never survived look-ahead, real fees or an out-of-sample test. quant-ring proves the discipline before trusting any strategy: one NautilusTrader engine runs the identical code in backtest and live, so there is no separate live version to drift out of sync with what got tested, and evaluate.py judges only on data a strategy has never seen.
02How it works
evaluate.py enforces an out-of-sample split, walk-forward validation across six windows, net-of-cost Sharpe, drawdown and an overfit detector, all covered by 24 tests. Two fighters went through it on two years of Binance BTCUSDT hourly data spanning a full cycle, a trend signal on an MA cross and a mean-reversion signal on a z-score, each judged at two cost levels, a 0.3% round trip and a stressed 0.4%. The public face is the Honest Backtester, a web tool where the browser runs its own calculation and matches the Python backtest to the digit.
03Outcome
Both fighters failed all four runs: the trend strategy lost 67.8% to 75.5% net of cost, mean reversion lost 52.4% to 66.7% and the published table lists every row rejected. No strategy has passed the out-of-sample bar yet, so nothing here trades real money. A negative result counts as money saved rather than money lost live. This is an internal research project, not investment advice. The next step is one new hypothesis under the same discipline, not a pile of parameter variations on the same data.
ANM SOLUTIONS / CONTACT US
First 30-minute call is free. We scope it, you decide.